The New Cloud Repatriation Strategy Isn’t About Cost
Every cloud repatriation strategy conversation happening in enterprise architecture right now sounds like it did in 2022 — until you listen closely to what’s actually driving the decision.
The Cost Wave
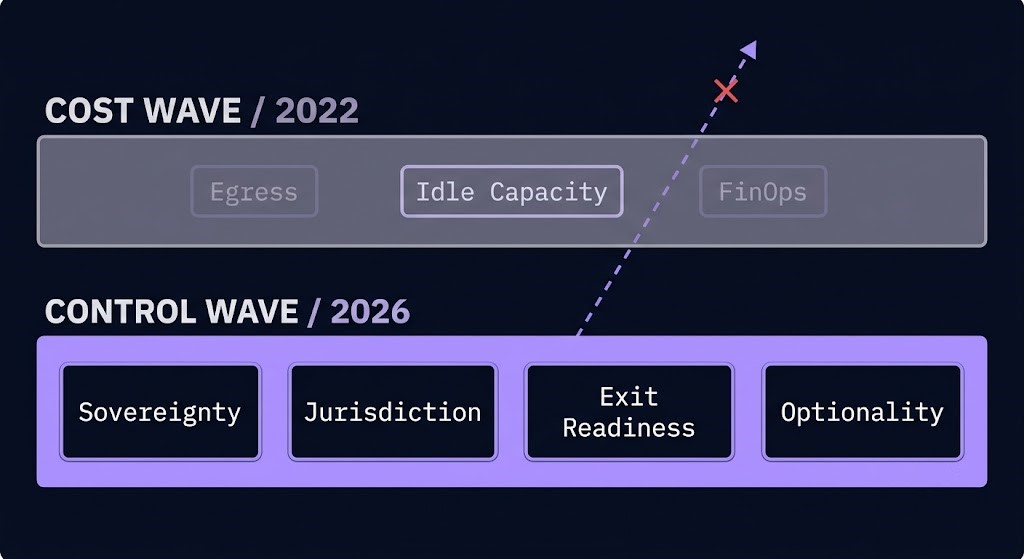
The first repatriation wave was a spreadsheet argument. Egress fees nobody modeled at design time. Idle reserved capacity nobody budgeted for after the initial sizing exercise — the same reservation-versus-reality gap Texas’s ERCOT grid queue exposed at a much larger scale in Phantom Capacity. A FinOps team that finally got a seat at the architecture table and started asking why a workload that ran fine on a $40,000 rack was costing $340,000 a year to run “elastically.” That wave produced real, defensible decisions — workloads with flat, predictable demand curves moved back on-prem, and the math held up under scrutiny.
But it was still, fundamentally, an optimization exercise. The question was never “should this workload live somewhere else.” The question was “is this the cheapest place for it to live.” Cost was the variable. Everything else — governance, jurisdiction, who actually controls the infrastructure underneath the workload — was assumed constant.
The workloads that actually moved back under that logic had a specific shape: steady-state, predictable, rarely bursty — batch processing, internal line-of-business applications, data warehouses running the same nightly job at the same scale every night. Nobody repatriated a genuinely spiky consumer-facing workload on cost grounds alone, because the elasticity argument still held there. Cost-driven repatriation was, correctly, selective.
That assumption is the thing that broke.
The Control Wave
Organizations are no longer asking where infrastructure is cheapest — they’re asking who controls it. In many cases, they are willing to spend more money to preserve that control.
That second sentence is the one worth sitting with, because it’s the actual evidence for the thesis. If cost were still the primary driver, organizations wouldn’t willingly accept a higher bill to get something else. But they are. Nutanix’s 2026 Enterprise Cloud Index found that 57% of organizations now feel the need to run infrastructure within a single country — domestically, whether on-prem or through a local cloud region — largely over security and data protection concerns, not price. Data sovereignty requirements, AI data-residency obligations, and jurisdictional exposure to foreign access laws are now architectural constraints in their own right, not footnotes to a TCO model.
The moment organizations started caring about preserving future choices rather than just minimizing this quarter’s bill, they also started rediscovering exit readiness — the uncomfortable realization that most of their “portable” architectures had never actually been tested against a real exit. That rediscovery is the thread this piece pulls on directly in a few sections.
What’s Actually Different This Time
The first repatriation wave was asking whether cloud economics worked. The current wave is asking whether cloud dependency remains acceptable. Those are different questions with different evidence requirements, and conflating them is exactly how you end up citing a 2022 egress argument to justify a 2026 sovereignty decision — and getting the architecture wrong as a result.
This isn’t the same argument made in The Repatriation Calculus, which was explicitly a cost-and-utilization exercise, or in the logic of when to move workloads on-prem, which was a workload-suitability framework. It’s also distinct from the AI infrastructure repatriation argument, which was driven by GPU economics specifically. This wave sits underneath all three — it’s the reason those workload-level decisions are increasingly being made in a jurisdictional and control context rather than a purely economic one. Getting there requires understanding movement architecture as a discipline in its own right, not just a migration project.
Control Is Not The Same Thing As On-Premises
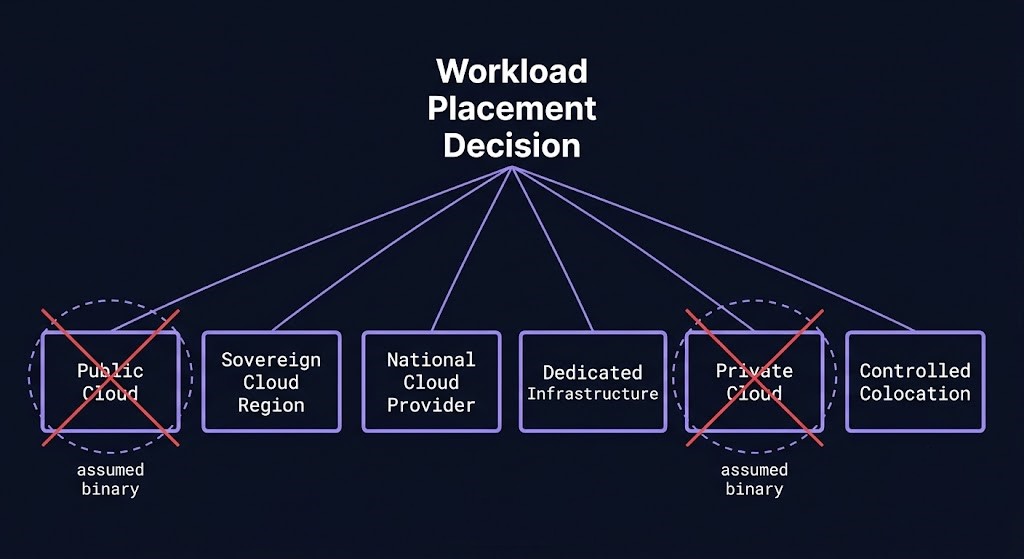
This is where most of the commentary on this shift gets it wrong. “Sovereignty,” “control,” and “repatriation” get mentally translated into “everything goes back on-prem” — and that’s not what the market is actually doing.
Control is being exercised through:
- Sovereign cloud regions — hyperscaler infrastructure operated under jurisdictional and legal separation from the parent entity
- National cloud providers — regional operators built specifically around single-country data residency
- Dedicated infrastructure — single-tenant capacity with contractual control guarantees a shared-tenancy model can’t offer
- Private cloud — cloud operating models run on infrastructure the organization owns or fully controls
- Controlled colocation — owned hardware in a facility chosen specifically for jurisdictional or connectivity guarantees
- AI placement architectures — deliberate decisions about where training and inference data physically live, independent of where the compute itself runs
None of these are “on-prem” in the traditional sense. All of them are control decisions. The architecture question isn’t cloud-versus-on-prem anymore — it’s which control model fits the actual constraint, and on-prem is just one option on a much longer list.
Airbus’s July 2026 sovereign cloud placement is a named example of that shape. According to The Register, the first 70 of 900 applications are moving to a European provider while platforms such as Skywise stay on AWS, and Airbus told the outlet it balances its choices by the criticality of the data. That is control layered onto an existing estate one workload at a time, not a move back on-prem, and what the public record does and doesn’t evidence about it is worked through separately.
Whichever model gets chosen, it’s still underwriting vendor trust in some form — a sovereign cloud region only delivers the jurisdictional separation it promises if the hyperscaler’s structural commitment holds once it’s actually tested by a foreign access request, and that’s a continuity question, not one that ends at contract signing. Every option on that list is still a concentration decision at some level — fewer providers, fewer regions, or fewer jurisdictions than the alternative — and pricing that concentration is what turns “we value control” into a number a board can weigh against the premium control costs.
The Exit Readiness Problem
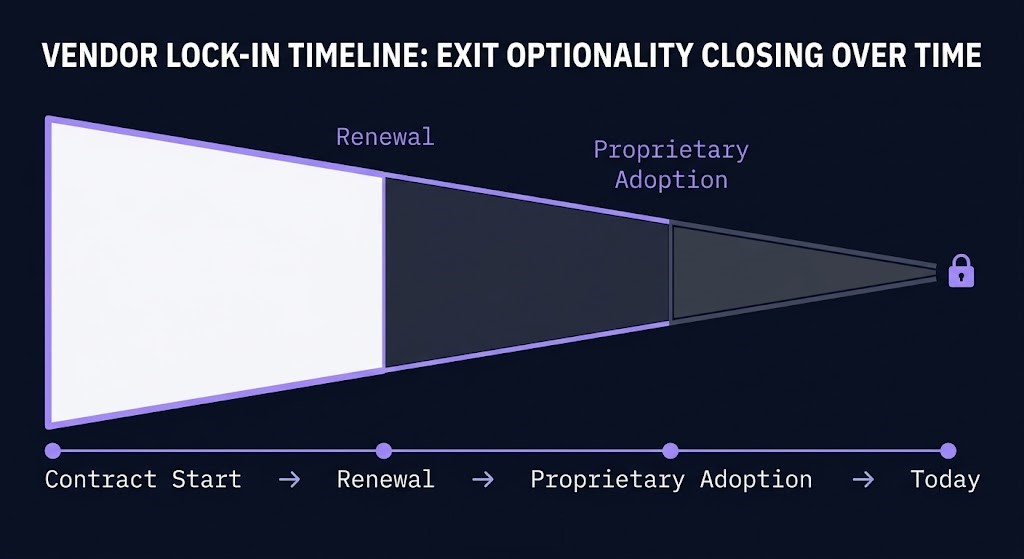
Preserving control only matters if the organization can actually act on it. That’s the expansion of the exit readiness point seeded above: most organizations that believe they’ve preserved optionality have never validated it under real conditions. An Exit Readiness Window closes quietly — contracts renew, proprietary services get adopted one convenience at a time, and the theoretical ability to leave erodes years before anyone tests it.
The erosion is rarely a single decision. It’s a managed database service adopted because it shaved two sprints off a project. A queueing service chosen because it was already in the console. A data pipeline that grew a dependency on a proprietary transformation layer nobody flagged as a lock-in risk at the time, because at the time it wasn’t one — the sovereignty requirement didn’t exist yet. Each choice was individually reasonable. Collectively, they’re why so many “portable” architectures fail the moment someone actually tries to exercise the exit.
This is the direct continuation of an argument made here: the first repatriation wave was an optimization discussion. The current wave is an optionality discussion. Optimization asks “is this efficient.” Optionality asks “can we still change our mind.” Sovereignty and control decisions are only real if the exit behind them is real — otherwise “control” is just a word on a slide, not an architectural property.
Where This Goes Next
Three things you’ll see more of over the next several quarters, in the order this argument actually predicts:
- Placement architectures that deliberately preserve exits — teams building explicit exit criteria into placement decisions at design time, not after the fact.
- Private cloud operating models — organizations rebuilding the operational discipline of cloud consumption (self-service, metering, elastic capacity) on infrastructure they control outright.
- Sovereign AI deployments — the most advanced manifestation of this trend, where jurisdictional control extends beyond storage location into how models are trained, governed, and run.
That ordering matters. Optionality comes first because it’s the precondition. The operating model comes second because it’s how optionality gets operationalized at scale. Sovereign AI comes last because it’s the hardest version of the same problem — control extended into the compute layer itself, not just the data layer.
This is squarely a Cloud Strategy problem, not an infrastructure-mechanics one: it’s about who holds authority over placement decisions, not how the workload gets physically moved.
Architect’s Verdict
Cost told you what was affordable. Control tells you what you’re actually allowed to do with what you’ve built.
The organizations getting this right aren’t reversing the last decade of cloud adoption — they’re layering a control requirement on top of it, workload by workload, without pretending the answer is always “bring it home.”
The first repatriation wave asked whether the cloud was worth the money. The current wave asks whether the organization still controls its future.
Additional Resources
View 6 more resources
Editorial Integrity & Security Protocol
This technical deep-dive adheres to the Rack2Cloud Deterministic Integrity Standard. All benchmarks and security audits are derived from zero-trust validation protocols within our isolated lab environments. No vendor influence.
R.M.
Senior Solutions Architect with 25+ years of experience in HCI, cloud strategy, and data resilience. As the lead behind Rack2Cloud, I focus on lab-verified guidance for complex enterprise transitions. View Credentials →
Get the Playbooks Vendors Won’t Publish
Choose the architecture problems you care about. Get field-tested playbooks and frameworks delivered to your inbox.
- > AI Infrastructure & Inference Economics
- > Cloud Strategy & Hidden Cost Models
- > Virtualization & Deterministic Migration
- > Kubernetes, IaC & Modern Infrastructure
- > Data Protection & Recovery Engineering
Zero spam. Includes The Dispatch weekly drop.
Need Architectural Guidance?
Independent review before major infrastructure decisions.
- > Validate assumptions
- > Identify hidden dependencies
- > Quantify migration risk
- > Challenge vendor narratives
Triage · Advisory · Fractional · Direct Hire