AI Infrastructure Is Becoming Critical Infrastructure. The Architecture Has to Change.
AI as critical infrastructure is no longer a metaphor — it’s an architectural condition with consequences, and a single reconsidered data-center campus just made that visible.
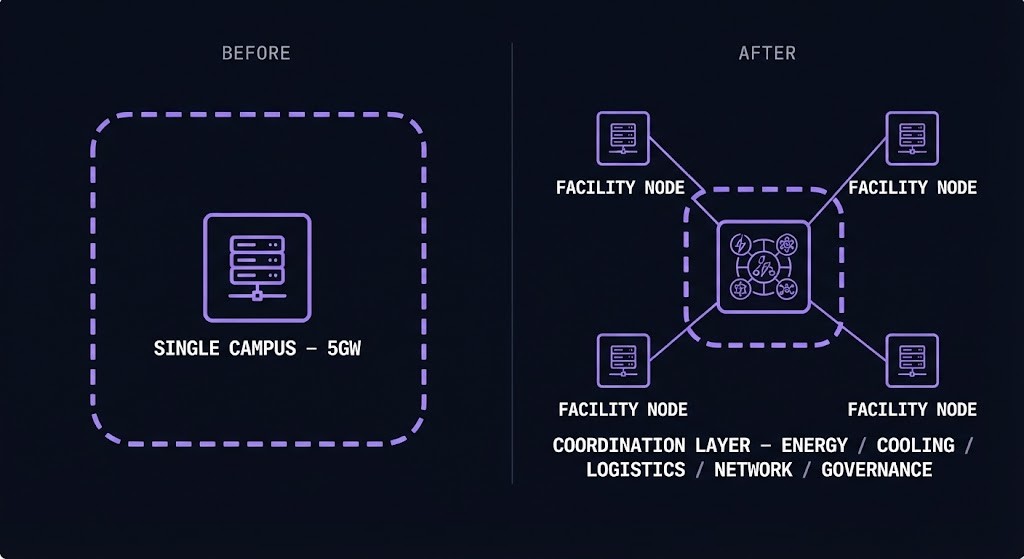
In September 2026, Reuters reported that the UAE was quietly revising plans for a 5-gigawatt AI data-center project after Iranian drone and missile attacks damaged AWS facilities in the UAE and Bahrain — two facilities directly struck in the UAE, a third damaged by a strike near a Bahrain site. The original single-campus concept, planned as a 26-square-kilometer site in Abu Dhabi, is reportedly giving way to a network of data centers spread across the country, with officials considering air defenses and underground construction to better protect the facilities.
The obvious read is a story about one campus, one region, one set of attacks. That’s not the interesting story. The interesting story is what the reconsideration itself reveals: AI infrastructure has crossed a scale threshold where physical resilience is a first-order architectural requirement, not an operational afterthought — and the architecture discipline built for cloud-era workloads was never designed for that requirement.
AI as Critical Infrastructure: A Different Class of Risk
For fifteen years, infrastructure architecture treated the physical facility as somebody else’s problem. Datacenter design optimized for uptime and power density. Cloud architecture optimized for regional resilience — availability zones, multi-region failover, the assumption that compute is fungible enough to move when a region has a bad day. Enterprise architects built on top of that assumption without needing to think about the substrate underneath it: the building, the grid connection, the water rights, the workforce that shows up to run it.
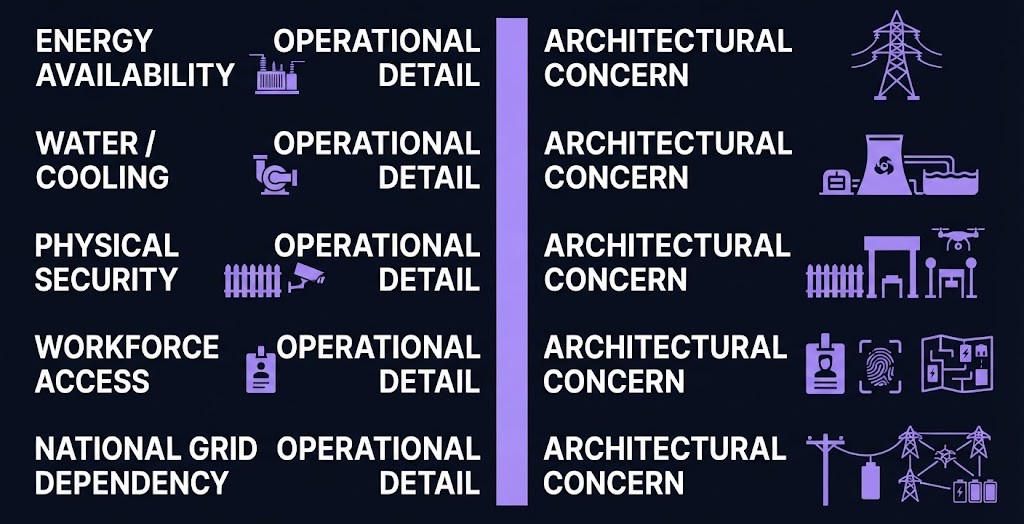
A single-digit-gigawatt AI campus breaks that assumption. At that scale, energy availability isn’t a line item — it’s a regional grid dependency measured against the same capacity utilities plan around for entire metro areas. Water for cooling is a watershed-level commitment. Physical security has to account for deliberate targeting, not just badge readers and fencing. Workforce access assumes a labor pool that can staff a facility the size of a small industrial complex, indefinitely.
None of that shows up in a Terraform plan or a cloud architecture diagram. It shows up in the same category of planning that power grids, telecommunications backbones, and transportation networks have always required — infrastructure whose failure doesn’t degrade a service, it degrades a region. That’s the actual claim behind AI as critical infrastructure: not that AI is important, but that AI infrastructure is now large enough to inherit the design constraints critical infrastructure has always carried, and enterprise cloud architecture has little native doctrine for them.
Why Distribution Looks Like the Obvious Answer
The instinctive fix, once you accept that a single campus is a single point of catastrophic failure, is to spread the load. Multiple sites instead of one. It’s the same instinct that produced multi-region cloud architecture, and Rack2Cloud has made the concentration-risk argument from a few different angles already.
The Cloud Concentration Risk argument prices this as a financial exposure — every placement decision is an implicit bet on how much capability sits behind a single point, and that bet has a dollar figure whether or not anyone calculates it. That post’s exposure formula is priced financially: the cost of an outage, expressed as a fraction of capability sitting behind one region or provider. What a 5GW campus forces is the same bet, priced physically instead: how much capability sits behind one building, one grid interconnect, one hazard zone.
A wildfire that came within a third of a mile of a Spokane VA medical center made the sharper version of this argument concrete: two facilities aren’t geographic redundancy just because they’re in different buildings. If they share the same power infrastructure, network carriers, workforce pool, transportation routes, or supplier base, a single regional event takes out the “redundant” pair together. Distance means nothing if the failure domain is bigger than the distance — the failure domain is defined by shared dependency, not miles on a map.
That’s the correct prior lesson, and it’s the one a naive read of the 5GW story would stop at: “distributed facilities aren’t automatically safer, because shared dependency reintroduces the concentration you thought you’d eliminated.” True, but it’s not where this story actually goes. It’s the bridge to the real architectural question, not the destination.
Distribution Creates a New Coordination Layer
Here’s what the naive version misses: when an organization deliberately designs for distribution from day one — not retrofitting redundancy onto an existing site, but building a distributed network as the primary architecture — it isn’t just multiplying the number of independent facilities. It’s building a new layer that didn’t exist when there was one campus.
The coordination layer is the set of systems, dependencies, and authorities that make physically distributed facilities operate as one AI system — not the sites themselves, but everything that has to hold for the sites to function as a single system rather than several unrelated ones.
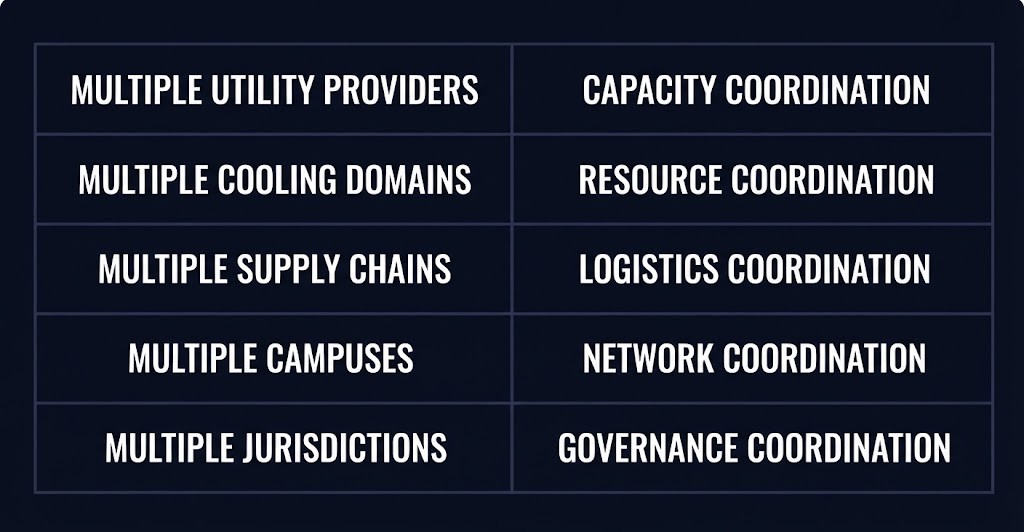
Multiple utility providers don’t eliminate energy risk — they create a capacity-coordination problem, because the campus’s actual power draw now depends on how load balances across grids with different regional constraints, different maintenance schedules, and different failure characteristics. Multiple cooling domains create a resource-coordination problem — water rights, thermal load, and maintenance windows now have to be managed across sites instead of within one. Multiple supply chains create a logistics-coordination problem — chips, cooling hardware, and spare parts now have to reach several locations on schedules that can desynchronize. Multiple campuses create a network-coordination problem — the sites only function as one AI system if the fabric connecting them holds, which means the interconnect is now as load-bearing as any individual facility. Multiple jurisdictions create a governance-coordination problem — different regulatory regimes, different utility contracts, different incident-response authorities, all of which now have to resolve to one accountable decision-maker when something goes wrong across all of them at once.
None of that coordination layer existed when the plan was a single 5GW site. It exists the moment the plan becomes a distributed network — and it exists whether or not anyone designed it deliberately. The architectural challenge was never really the facilities themselves. It’s the layer that makes them operate as one system.
Oracle’s $7 billion Wisconsin power guarantee is the same pattern from the other direction — a site-selection decision that looks like a power story but is really a commitment story, the economic cost of anchoring a campus to one location. The 5GW campus reconsideration is the mirror case: instead of committing to one location’s constraints, it’s distributing across several — and inheriting a coordination cost in exchange for a concentration discount. Neither move is free. Phantom Capacity showed the same lesson one layer earlier, in demand signal rather than site architecture: Texas couldn’t tell real compute demand from noise, because the systems tracking capacity weren’t built for AI’s actual consumption pattern. The pattern repeats at every layer this industry touches — the tooling built for the previous scale doesn’t natively see the problem at the new one.
The New Failure Domain
This is the direct extension of the geographic-redundancy lesson, not a restatement of it. The earlier analysis established that the failure domain is defined by shared dependency, not distance. The 5GW case adds the layer that argument didn’t need to cover, because it was diagnosing an already-built pair of sites, not a system designed for distribution from the start.
This is where AI as critical infrastructure stops being a framing device and becomes a literal architectural requirement. Once a campus becomes a deliberately distributed network, the failure domain isn’t the individual site anymore — hardening one building against blast, fire, or flood doesn’t answer the real question. The failure domain is the coordination layer itself: the capacity-balancing logic across utilities, the interconnect fabric across sites, the incident-response authority across jurisdictions. It’s the same test Backup Blast Radius applied to recovery infrastructure — blast radius follows the dependency graph, not physical topology — run here prospectively, at design time, instead of diagnostically, after something’s already failed. If that layer has a single point of failure — one control system, one authority, one network path that all the sites route through — then the organization has rebuilt the exact concentration problem it just spent enormous capital “solving,” one layer up, where it’s harder to see and wasn’t in the original threat model at all.
The architectural conclusion isn’t “distribute your AI infrastructure.” It’s this: once you distribute deliberately, the coordination layer you just created has to be evaluated as a first-class part of the architecture — designed with the same rigor as the facilities it connects — not treated as an operational detail that inherits safety by association with the sites it’s supposedly protecting.
Architect’s Verdict
AI as critical infrastructure does not stop being concentrated when facilities become distributed. Concentration moves upward, into the systems coordinating energy, connectivity, logistics, and governance across those facilities — and that layer inherits none of the hardening the individual sites get, unless someone deliberately puts it there.
Most organizations treat physical distribution as the finish line. Multiple sites, multiple utilities, multiple jurisdictions — the box gets checked, the exposure looks diversified, and nobody goes back to ask what binds the sites into one system, or what happens to the whole campus network if that binding layer fails. That’s the actual gap: the industry has decades of doctrine for hardening individual facilities, but far less established doctrine for hardening the coordination layer above them.
As AI infrastructure continues to inherit the scale and threat model of critical infrastructure, that coordination layer stops being an operational detail and becomes the architecture.
Additional Resources
Editorial Integrity & Security Protocol
This technical deep-dive adheres to the Rack2Cloud Deterministic Integrity Standard. All benchmarks and security audits are derived from zero-trust validation protocols within our isolated lab environments. No vendor influence.
R.M.
Senior Solutions Architect with 25+ years of experience in HCI, cloud strategy, and data resilience. As the lead behind Rack2Cloud, I focus on lab-verified guidance for complex enterprise transitions. View Credentials →
Get the Playbooks Vendors Won’t Publish
Field-tested blueprints for migration, HCI, sovereign infrastructure, and AI architecture. Real failure-mode analysis. No marketing filler. Delivered weekly.
Select your infrastructure paths. Receive field-tested blueprints direct to your inbox.
- > Virtualization & Migration Physics
- > Cloud Strategy & Egress Math
- > Data Protection & RTO Reality
- > AI Infrastructure & GPU Fabric
Zero spam. Includes The Dispatch weekly drop.
Architecture Audit Services
Fixed-scope audits for Zero-Trust Azure, VMware migration readiness, and recovery posture — no discovery call required to start.
>_ View Audit Services>_Related Posts
Your Vendor Review Process Never Saw The Real Supplier
Every vendor review process assumes it’s evaluating a supplier — but a scan finding foreign-origin code embedded in more than one in eight mobile apps used by US military personnel makes the actual assumption visible: organizations review the company they bought from, not the code that arrived inside what they bought. >_ Architect’s Brief 60-second…
Your Monitoring Didn’t Miss the Incident. It Was Never Designed to See It.
I’ve watched observability vs monitoring play out as a live incident more times than I can count. >_ Architect’s Brief 60-second read before you commit to the full post · Full post: 10 min Generating brief… The dashboard was green. The on-call engineer was not paged. The monitoring system did exactly what it was designed…
Your Kubernetes Cluster Isn’t Out of CPU — The Scheduler Is Stuck
Compute Tier 1 Authority Cascades to ➔ >_ Architect’s Brief 60-second read before you commit to the full post · Full post: 9 min Generating brief… [Storage] [Network] 🚨 Failure Signature Detected Grafana shows cluster CPU utilization is under 50%, but pods are stuck in Pending. Events show: 0/10 nodes are available: 10 Insufficient cpu….
Your Identity System Is Your Biggest Single Point of Failure
Part 2 of the Rack2Cloud’s Cloud Fragility Series >_ Cloud Fragility Series 01 Multi-Cloud Cascading Failure Risks 02 Your Identity System Is Your Biggest Single Point of Failure [CURRENT] 03 Vendor Lock-In Happens Through Networking — Not APIs 04 Your Cloud Bill Quietly Increased in 2026 — Here’s Where the Money Is Actually Going >_…
Your Identity Provider Was Never Your Spend Boundary
Every enterprise cloud governance program assumes a spend boundary sits somewhere between identity and money — a checkpoint that catches compromised access before it becomes compromised spend. It doesn’t exist. Not as a distinct control. Not as a separate policy layer. Not anywhere in the architecture most organizations have actually built. >_ Architect’s Brief 60-second…
Your Identity Controls Passed. Your Authorization Chain Failed.
A credential chain functioned exactly as it was designed to. No firewall failed. No exploit executed. No malware bypassed a control. A red team walked past physical and social barriers using nothing more exotic than a plausible pretext, and came out the other side holding network admin credentials — issued correctly, authorized correctly, working exactly…