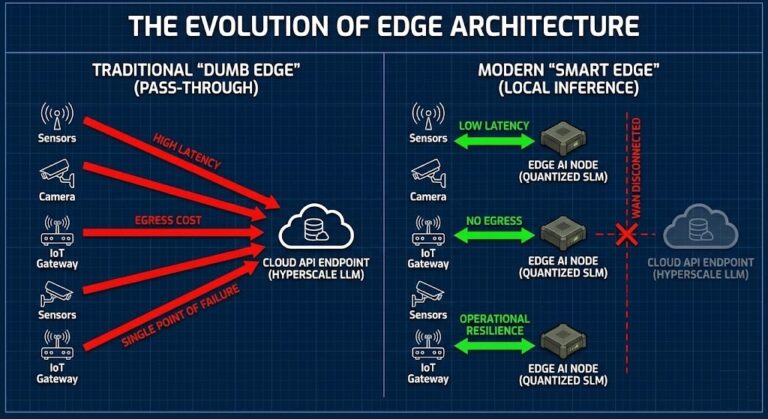
The Disconnected Brain: Why Cloud-Dependent AI is an Architectural Liability
This is Part 2 of the Rack2Cloud AI Infrastructure Series. Catch up on Part 1: TPU Logic for Architects: When to Choose Accelerated Compute…
READ MORE →ENGINEERING NOTES FROM THE COMPLEXITY GAP.
The journey from legacy infrastructure to modern cloud-native platforms is often obstructed by marketing-driven abstraction and tool-centric noise. Most technical journals focus on the "Day-1" installation — the easy path. Rack2Cloud documents the Day-2 production reality. We analyze how systems actually behave under load, at the boundaries of integration, and within the constraints of sovereign requirements.
Our field notes serve as a deterministic guide for the architect navigating the complexity gap. We prioritize the physics of data and the logic of high availability over vendor checklists.
"In production, complexity is the default state; architecture is the only defense."
This is Part 2 of the Rack2Cloud AI Infrastructure Series. Catch up on Part 1: TPU Logic for Architects: When to Choose Accelerated Compute…
READ MORE →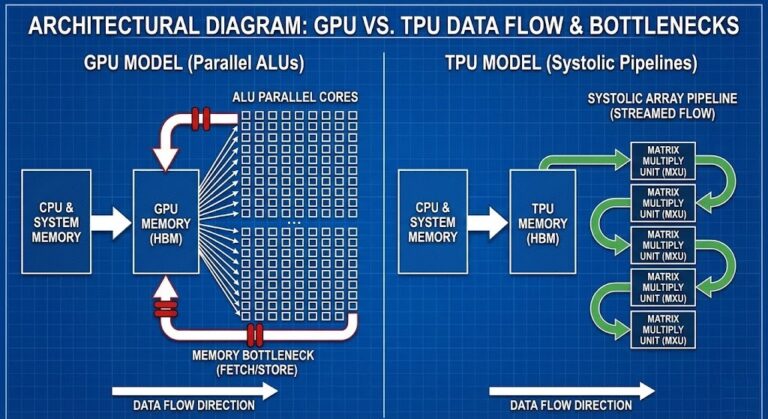
This is Part 1 of the Rack2Cloud AI Infrastructure Series. To understand how to deploy these models outside the data center, read Part 2:…
READ MORE →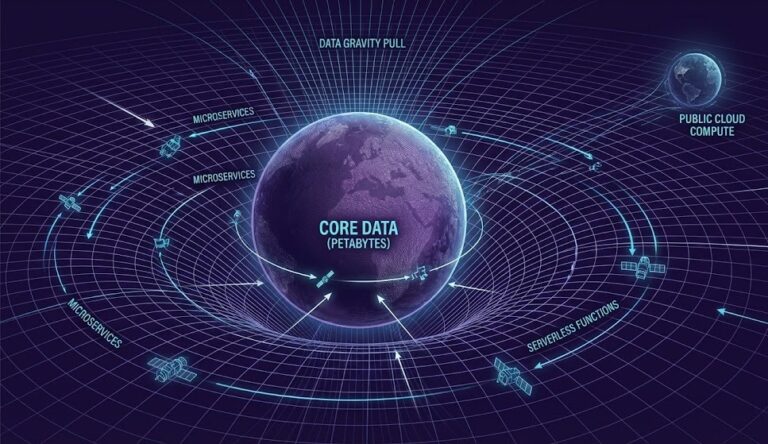
Hybrid cloud isn’t a compromise. It’s what happens when latency, bandwidth, and economics converge. For a decade, the industry operated under a simple assumption:…
READ MORE →
The case for Ceph NVMe AI training storage doesn’t start with a spec sheet comparison. It starts with a scale threshold. There is a…
READ MORE →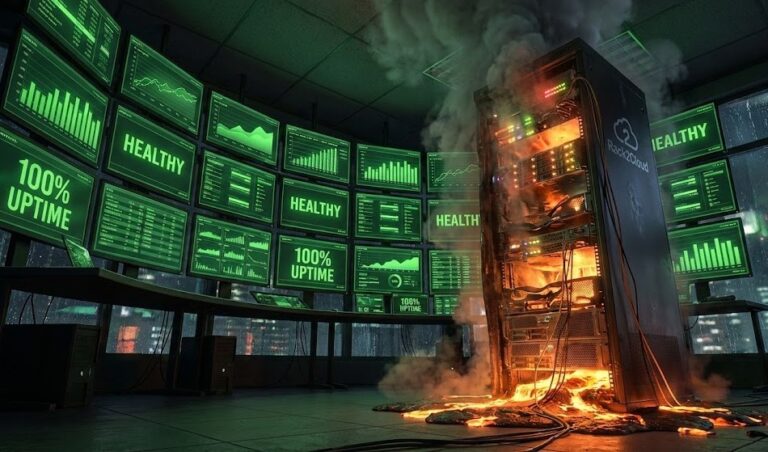
It’s 3:00 AM. No calls, no alerts, everything looks spotless. The error rate is zero, p99 latency is a breezy 45ms, CPU and memory…
READ MORE →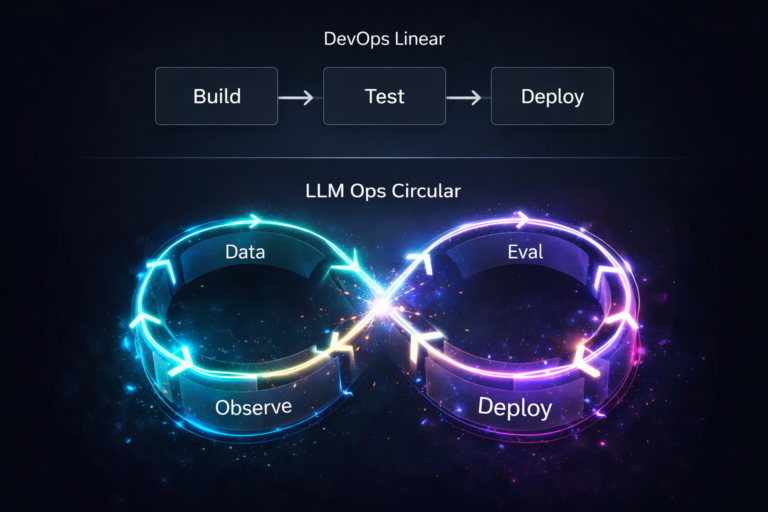
The incident ticket looked fine. >_ Architect's Brief Architecture overview before you dive in · Full post: 6 min Generating brief... For years, every…
READ MORE →
The “Samsung Moment” Building sovereign AI infrastructure means keeping your most sensitive data on hardware you control — not feeding it to a public…
READ MORE →
The NCCL Timeout Nightmare GPU fabric physics is where $50 million clusters go to die. You wired up 800G OSFP optics, fired up your…
READ MORE →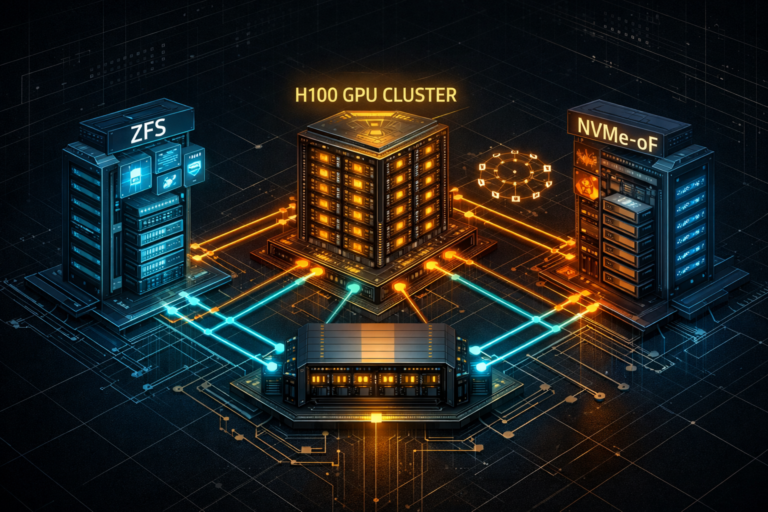
The Real Problem: The “Checkpoint Stall” A 16x H100 cluster costs roughly $40/hour to sit idle. When your AI training storage can’t ingest a…
READ MORE →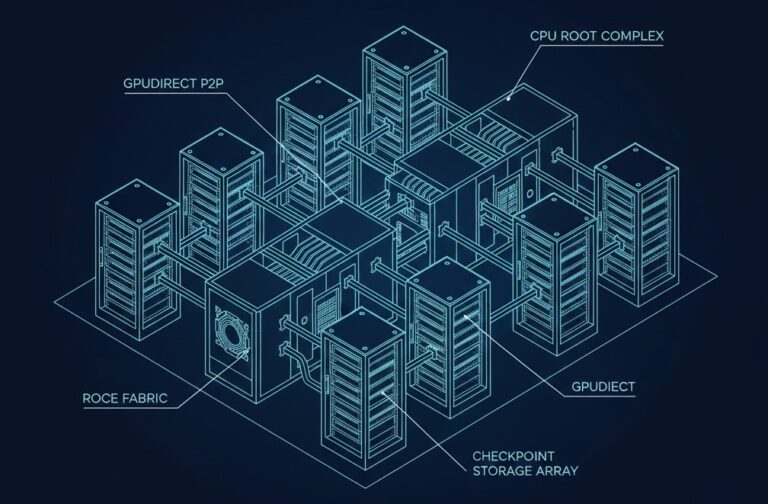
Building a cluster for inference is a weekend project. Building one for distributed training is a war of attrition against physics and “standard” enterprise…
READ MORE →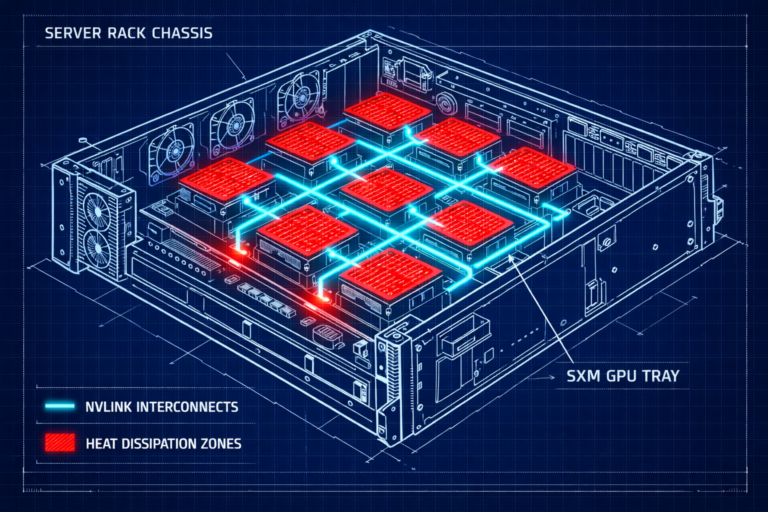
Private AI infrastructure is systems engineering, not optimization. If you treat a GPU cluster like a standard virtualization farm, you will fail. I have…
READ MORE →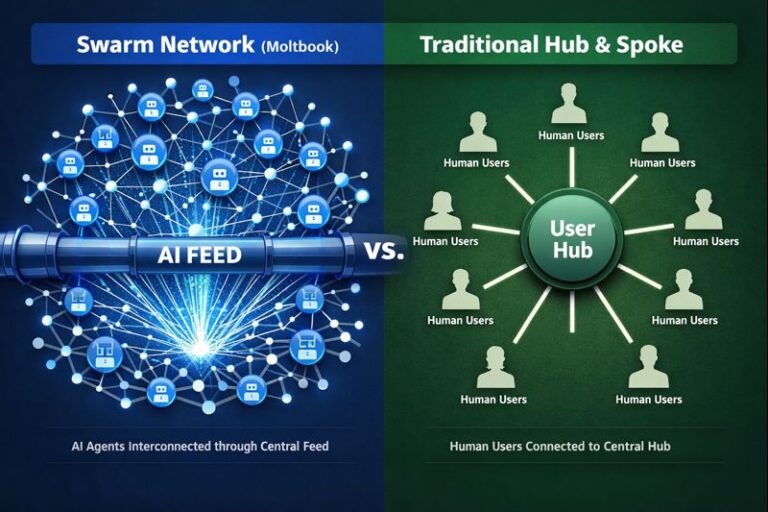
Moltbook AI agents now number over 1.4 million — autonomous bots sharing a live feed, broadcasting runnable prompts, code fragments, and behavioral templates to…
READ MORE →