The Cost of Idle Capacity Nobody Budgets For
Idle capacity shows up on every utilization dashboard the same way: as a number that should be lower. Most infrastructure cost reviews ask why the organization is paying for capacity nobody is using. Architects should be asking a different question — what would become impossible tomorrow if that capacity disappeared tonight.
That question rarely gets asked, because finance and architecture aren’t measuring the same thing. Finance measures consumption. Architecture manages optionality — the same currency the entire discipline has quietly started rewarding over efficiency. Idle capacity sits exactly on the seam between those two disciplines, and most organizations resolve the disagreement by defaulting to whichever one has a dashboard.
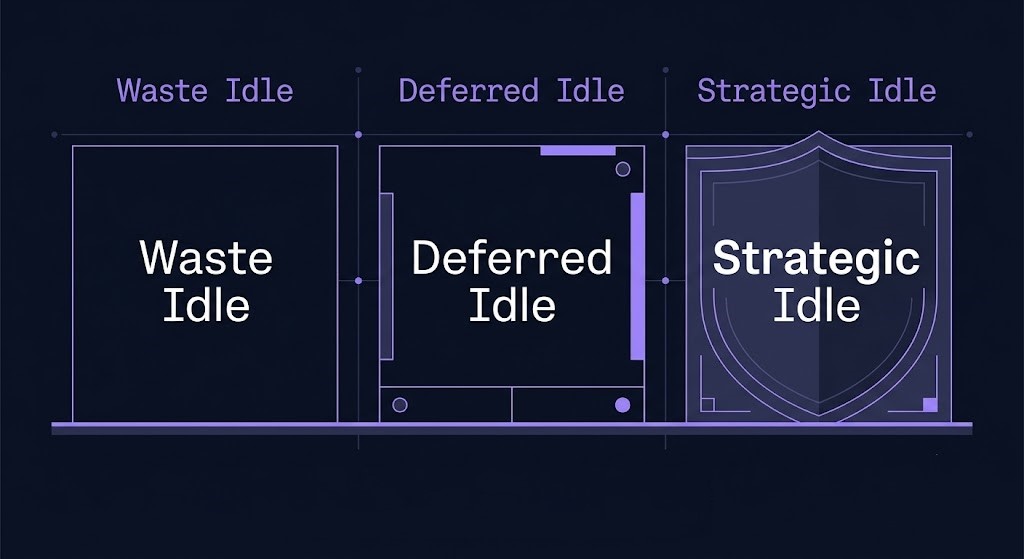
Idle Capacity Is Not One Category
Treating all idle capacity as a single line item is the root of the disagreement. In practice, idle capacity in any enterprise cloud strategy splits into three distinct categories, and they don’t behave the same way:
| Type | Meaning |
|---|---|
| Waste Idle | Nobody needs it. No plan, no owner, no future use. |
| Deferred Idle | Planned future use. A roadmap item, not yet consumed. |
| Strategic Idle | Preserves architectural options. Exists specifically so a future decision remains possible. |
Most reporting systems can’t tell these apart. A GPU pool waiting on next quarter’s model rollout, a DR environment that hasn’t failed over in eighteen months, and a genuinely abandoned dev cluster all show up as the same red number on the same dashboard.
Why Utilization Dashboards Flatten the Difference
Utilization dashboards are built to answer one question — how much of what we bought is being consumed right now. That’s a reasonable question for Waste Idle. It’s the wrong question for Strategic Idle, because Strategic Idle isn’t supposed to be consumed. Its value comes from existing, not from being used.
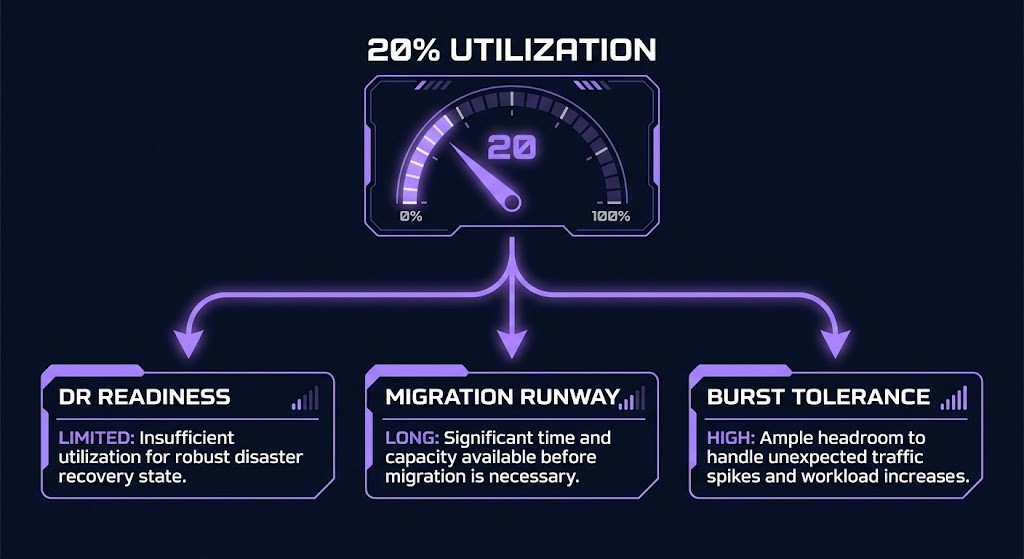
Finance sees 20% utilization on a standby cluster and reads it as underinvestment recovery. Architecture reads the same number as DR readiness, migration runway, burst tolerance, and procurement lead-time protection — four different forms of risk that have nowhere else to be recorded.
The Accounting Problem
The disagreement isn’t really about the number. It’s about where the number lives. Accounting systems recognize idle capacity as cost, full stop — it appears on a bill, and bills get scrutinized. Architecture recognizes the same capacity as optionality, but optionality has no line item. It doesn’t appear anywhere until the moment it’s needed, and by then it’s too late to argue for keeping it.
That asymmetry is why idle-capacity conversations go badly by default. Cost is visible every month. Optionality is invisible until a migration, an incident, a procurement delay, or a demand spike makes its absence sudden and expensive. Without naming that asymmetry directly, “this idle capacity is valuable” sounds like rationalized waste. With it named, the distinction is much harder to dismiss.
That asymmetry describes what happens after capacity exists. A related piece, The Capacity You Paid For But Never Used, goes back one step further — to the commitment decision itself, before the capacity that eventually shows up as Waste, Deferred, or Strategic Idle was ever purchased. Its argument: the decision models that authorize capacity commitments are typically thorough about the cost of running short, and structurally silent about the cost of being wrong in the other direction. A third piece goes back further still: Phantom Capacity examines what happens before even the commitment decision — when a reservation enters a planning system with no proof it represents real intent, the ERCOT interconnection-queue failure Texas is now confronting.
Wisconsin shows what happens when that upstream validation gap gets closed by force rather than by governance. Oracle’s Wisconsin power guarantee converts an unresolved demand forecast into a priced financial obligation before the underlying capacity has had any chance to become Waste, Deferred, or Strategic Idle at all — a fourth outcome this typology doesn’t cover, because the commitment never gets the chance to sit unused and get judged. It gets priced as a liability while still pending.
Google’s TPU rationing is the clarifying edge case for this whole typology: a system with no Waste, Deferred, or Strategic Idle left to classify, because every unit of capacity is already spoken for by real, confirmed demand. There’s no dashboard argument to have about whether Google’s TPU fleet is secretly valuable idle capacity — it isn’t idle at all, anywhere, which is exactly why Meta got rationed and Google had to lease external GPUs to cover the gap. Strategic Idle only exists as a category because most infrastructure isn’t running at that edge. Google’s currently is.
Where Strategic Idle Actually Shows Up
A migration landing zone is the clearest version of this pattern. Provision the environment, size it for a cutover, and then watch it sit almost untouched for months — a utilization report will flag it as waste every single cycle. What it actually is: a pre-positioned execution environment that can pull hundreds of production workloads off a platform under commercial or contractual pressure, on short notice, without a scramble to provision first. The month it’s needed is the month the “waste” argument disappears entirely.
The same pattern recurs across DR environments sized for a failover that hasn’t happened yet, reserved GPU pools held for a project that hasn’t kicked off, and cloud burst capacity purchased for a peak that only materializes twice a year. None of it is being consumed on the dashboard’s terms. All of it is doing its job.
Two-node edge clusters are the same pattern with the clock running faster. Two Nodes Can Preserve Availability. They Can’t Preserve N+1 Capacity. covers Red Hat’s own recommendation to size each node at roughly 50% utilization — headroom that reads as waste on any dashboard checked before a failure and reads as the entire reason the architecture survived on any dashboard checked after one. It’s Strategic Idle with a failure domain attached instead of a roadmap date.
A vendor-side version of the same pattern showed up recently, distinct from the buyer-side instances above. Proxmox’s Arm64 Bet Runs On Lifecycle Parity, Not A Feature Release covers a hypervisor vendor funding full lifecycle parity — validation, drivers, documentation, support staffing — on a second CPU architecture years before customer demand on that architecture would justify the spend on a pure utilization basis. Read on a feature-adoption dashboard, that spend looks like waste: almost nobody is running Grace or Vera hardware today. Read as Strategic Idle, it’s optionality the vendor is deliberately keeping open against its own single-architecture dependency, for exactly the reason this post argues idle capacity shouldn’t be judged by current consumption alone.
That GPU example matters beyond this typology. The same reserved-and-idle signature — accelerator fleets sitting at extremely low utilization while teams simultaneously queue for more capacity — is also the sprawl-phase evidence this site’s AI infrastructure consolidation cycle analysis uses to argue AI infrastructure is running the same five-stage sequence virtualization already completed. The two readings aren’t in tension. Whether a given idle GPU pool is Strategic Idle or sprawl-phase acquisition outpacing governance is exactly the distinction an allocation review is supposed to make — and most organizations aren’t running that review yet.
The Queue–Idle Paradox
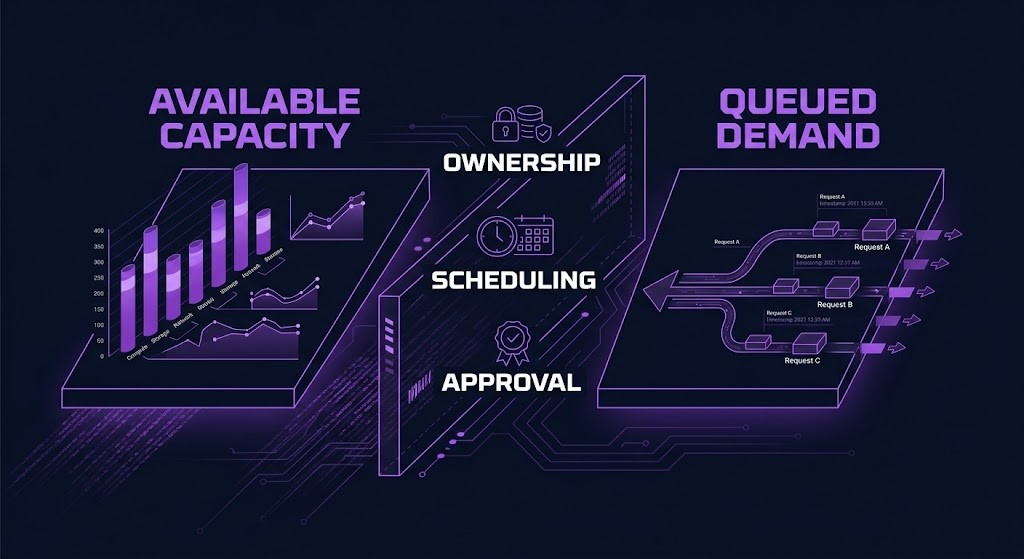
This is where the pattern connects to existing doctrine rather than requiring a new one. The interesting failure mode isn’t capacity sitting empty — it’s capacity sitting empty while demand is queued right next to it. Capacity exists. Demand exists. The work still doesn’t happen. That’s not a capacity problem. It’s a governance and allocation problem — ownership, scheduling, and approval friction standing between resources that exist and work that’s waiting.
It’s worth being precise about how this differs from the adjacent failure mode already named in the framework registry:
| Framework | Question It Asks |
|---|---|
| Capacity Illusion Index | Why do we think we have capacity when we don’t? |
| Strategic Idle | Why do we think unused capacity has no value when it does? |
They’re inverse problems. Capacity Illusion Index is about capacity that looks available but can’t actually be consumed. Strategic Idle is capacity that can be consumed, and isn’t — deliberately — because consuming it now would spend the option it exists to preserve.
Many of the environments that score poorly on Effective GPU Yield and exhibit signs of Phantom Scarcity are simultaneously carrying significant Strategic Idle. The contradiction isn’t technical. It’s organizational — the same environment can be under-provisioned in one dimension and idle-rich in another, because nobody is tracking either one as the same conversation.
Architect’s Verdict
Idle capacity is not a single problem, and it doesn’t deserve a single answer. Treating Waste Idle, Deferred Idle, and Strategic Idle as the same line item is how organizations cut the thing that was protecting them and keep the thing that wasn’t.
The real failure isn’t that idle capacity exists. It’s that no system in most organizations is built to tell the three types apart before the budget conversation happens — so the cut gets made on a utilization number instead of an architectural one.
The question isn’t why you’re paying for idle capacity. The question is what decision becomes impossible if you remove it.
Additional Resources
View 6 more resources
Editorial Integrity & Security Protocol
This technical deep-dive adheres to the Rack2Cloud Deterministic Integrity Standard. All benchmarks and security audits are derived from zero-trust validation protocols within our isolated lab environments. No vendor influence.
R.M.
Senior Solutions Architect with 25+ years of experience in HCI, cloud strategy, and data resilience. As the lead behind Rack2Cloud, I focus on lab-verified guidance for complex enterprise transitions. View Credentials →
Get the Playbooks Vendors Won’t Publish
Choose the architecture problems you care about. Get field-tested playbooks and frameworks delivered to your inbox.
- > AI Infrastructure & Inference Economics
- > Cloud Strategy & Hidden Cost Models
- > Virtualization & Deterministic Migration
- > Kubernetes, IaC & Modern Infrastructure
- > Data Protection & Recovery Engineering
Zero spam. Includes The Dispatch weekly drop.
Need Architectural Guidance?
Independent review before major infrastructure decisions.
- > Validate assumptions
- > Identify hidden dependencies
- > Quantify migration risk
- > Challenge vendor narratives
Triage · Advisory · Fractional · Direct Hire