The Architecture of Premature Closure
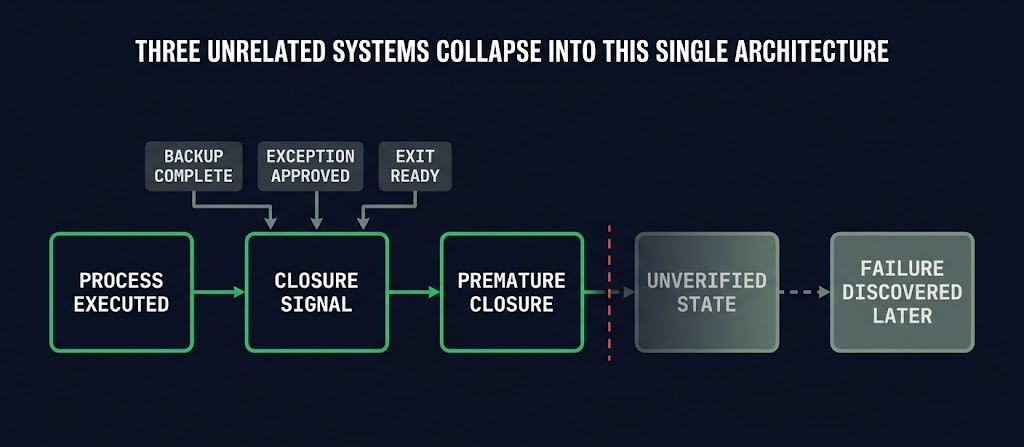
Premature closure is the pattern behind the failures your monitoring never saw coming. It happens when a system declares success because a process executed, even though the state the process was meant to create was never verified. The dashboard goes green. The ticket closes. The exception gets approved. None of that means the thing you actually needed to happen, happened — it means the mechanism that was supposed to make it happen ran to completion. Those are different claims, and enterprise infrastructure is full of places where the two get treated as interchangeable.
Three Systems, One Failure Mode
Three examples make this impossible to write off as a backup-specific quirk.
In data protection architecture, the backup success-rate metric reports the outcome the pipeline was built to produce — a completed backup job — without touching the question a recovery actually depends on: whether the data restores. The job can succeed a thousand times in a row and still fail the one time someone needs the restore, because “the job ran” and “the data comes back” were never the same test.
In Modern Infrastructure & IaC, Emergency Reconciliation Gap describes the identical shape one layer up, at exception management. An emergency change gets an authorized bypass, and the approval itself becomes the closure signal. Nothing in that mechanism requires the exception to actually return to a governed, IaC-tracked state — Bypass Authority, Change Latency Budget, Reconciliation Ownership, and Closure Deadline all have to be explicitly assigned, or the exception just stays open indefinitely: technically approved, never reconciled. That failure state has a name — Permanent Exception — and it’s premature closure wearing a change-management badge.
In Cloud Strategy, the same shape shows up one layer further up the stack: an organization declares a system portable, treats the declaration as proof of an exit path, and only discovers the real question — can this system actually be pulled out and stood up elsewhere without a controlled failure — the first time someone tries it for real. “Portable” was a design intent. It was never validated as an executable exit.
| Domain | Closure Signal | Real Validation Missing |
|---|---|---|
| Recovery | Backup completed | Restore proven |
| Governance | Exception approved | Reconciliation completed |
| Cloud Strategy | Exit readiness declared | Exit survivability proven |
A fourth domain belongs on this table: disaster recovery specifically. A technically clean failover is its own closure signal — the workload comes back, the dashboard goes green — while the actual claim that matters, whether the business is operating, goes unverified. The Continuity Execution Boundary (#163) names that gap directly, and it’s the anchor framework for the Disaster Recovery & Failover Architecture stage.
A fifth domain sits above all four: whether the evidence behind any of these closure signals — the completed backup, the approved exception, the declared exit, the clean failover — was ever examined by a party structurally independent of whoever produced it. Data Protection’s Governance & Recovery Assurance stage names that condition Evidence Theater, and it’s the pattern this entire post describes, generalized one layer further: a closure signal is premature not just when the underlying state was never verified, but when nobody with actual standing to reject the claim was ever given the chance to check it.
A sixth domain belongs on this table too, one that inverts the others slightly: in governance standards, the closure signal isn’t a dashboard or an approval record — it’s the document itself, still sitting at the same URL, unedited, looking exactly as authoritative as the day it was published. Infrastructure Standards Without Enforcement Become Documentation Debt names that specific case: a standard nobody has re-verified against deployed reality, treated as current because nothing ever forced the question. The process here isn’t even a process running to completion — it’s the absence of one, which makes it the quietest version of premature closure on this list.
A seventh domain sits outside the technical stack entirely, in the contractual layer: closure signals that vendors are contractually entitled to reject. Vendor Relationships End. Audit Rights Often Don’t. covers a case where the closure signal — “we removed the platform” — was declared internally and accepted as final, while a licensing agreement’s audit-rights and record-retention clauses kept the exit open on a separate clock the infrastructure team never owned. Same failure shape as the rest of this table: a process ran (the migration), a signal fired (platform removed), and the party with actual standing to dispute the claim — the vendor’s legal team, this time, not an internal reviewer — was never structurally positioned to check it before the closure was declared complete.
An eighth domain sits inside incident response specifically: closure signals built from remediation actions completing, not from the compromise actually being over. The Server Was Fixed. Persistent Access Wasn’t. documents a case where credential rotation and a full server rebuild both executed cleanly — the recovery process’s own closure signal — while the actual claim, whether the attacker still had a way in, went unchecked, because the mailbox-permission layer where persistence lived was never inside either remediation action’s scope. Same shape as the rest of this table: the process ran, the signal fired, and the unverified state surfaced only once someone went looking for it directly.
Worth drawing a boundary here rather than adding a ninth row to the table above: Dependency Residue (#77) is not this pattern. Every domain above fails because the closure signal was never checked against the state it claimed to represent. Residue’s cost model is checked and correct — it accurately reports what it was scoped to measure. The failure is upstream of verification: the model’s boundary was drawn around the thing declared eliminated, and a dependency the program never disputed keeps running, billing, or being owed outside it. Premature closure is an unverified claim. Residue is a verified claim measuring the wrong perimeter.
The same shape turns up in identity infrastructure, where the closure signal is a vendor-scheduled remediation rather than a ticket. DKM ACL hardening for AD FS has a published October 2026 enforcement date. The update installs and remediation runs. The state it was meant to produce is one permission on an Active Directory container, and the record of the value it replaced is an event in a log that rolls over. The closure signal says the update ran. Only the ACL and the preserved event text say what changed.
01 — PROCESS EXECUTED
The mechanism runs to completion — the backup job finishes, the exception gets approved, the migration executes.
02 — CLOSURE SIGNAL FIRES
Something reports “done” — a green dashboard, an approval record, a completed migration ticket — based on execution, not outcome.
03 — PREMATURE CLOSURE
The system treats the closure signal as equivalent to the state it was meant to represent. No mechanism distinguishes the two.
04 — UNVERIFIED STATE
The actual condition — restorable data, reconciled configuration, survivable exit — remains unknown, carried forward as an assumption.
05 — FAILURE DISCOVERED LATER
The gap surfaces during the incident, the audit, or the exit — at the most expensive possible moment to discover it was never closed.
Premature Closure Is an Architectural Failure
None of these are operator mistakes. Nobody signing off on a green backup dashboard, approving an emergency exception, or declaring a migration “portable” is being careless — the mechanism they’re operating is doing exactly what it was built to do. That’s what makes premature closure an architectural failure rather than a training problem. A closure condition is a design decision made when the system is built, usually early, usually under time pressure, usually optimizing for “can we tell this finished” rather than “can we prove this succeeded.” Once that decision is baked into the pipeline, every downstream operator inherits it as ground truth. They aren’t failing to check the state — the system was never instrumented to expose whether the state existed in the first place.
⚠ COMMON MISTAKE
Treating a green status as evidence of a validated state, rather than evidence that the checking mechanism itself executed. A backup can report success, an exception can carry an approval record, and a migration can close its ticket — all while the state each was meant to guarantee remains completely unverified.
Systems Optimize for Cheap Signals
Premature closure repeats because measurable completion is cheap and verified end-state is expensive, and every closure condition in production infrastructure is a bet on which one gets built.
Backup completed. Ticket closed. Exception approved. Migration finished. Deployment succeeded. Every one of those signals is measurable in real time, off data the pipeline already produces as a side effect of running. None of them requires an additional system — no restore test harness, no reconciliation audit, no post-migration validation suite. The moment a team has to choose between shipping the cheap signal now or building the expensive verification later, the cheap signal ships. Not out of negligence — because it’s the only thing available to report at the point the process needs to say something.
This is the same shape Infrastructure Evidence Gap names at the pipeline layer: a pipeline can be green and fully reproducible while carrying zero externally-readable proof that its output was ever authorized against what was actually reviewed. Execution and evidence are different claims, and the pipeline was only ever instrumented to report the first one.
Restore evidence makes the same point from the DR side — it’s the artifact missing from almost every disaster recovery program, not because nobody thought of it, but because a completed backup job is so much cheaper to produce and report than a proven restore. And the recoverability gap shows the downstream cost: a ransomware recovery plan that looks complete on paper because every box the plan asked for got checked, with no mechanism forcing the check itself to mean anything.
The check that actually forces meaning onto itself is the adversarial one. Adversarial restore testing is verification discipline applied specifically to recovery: a restore drill that only runs under cooperative conditions is still a cheap signal wearing a green checkmark, no matter how thoroughly it was executed — the expensive, real verification is whether it survives someone actively working against it.
None of this is a case for distrusting automation. It’s a case for noticing that automation reports what it was built to measure, and closure conditions are one of the cheapest things to under-specify at design time — because under-specifying them doesn’t break anything visibly. The pipeline still runs. The dashboard still turns green. The gap only becomes visible at the worst possible moment: during the incident, the audit, or the exit, when someone finally needs the state the signal claimed to represent.
Verification Discipline
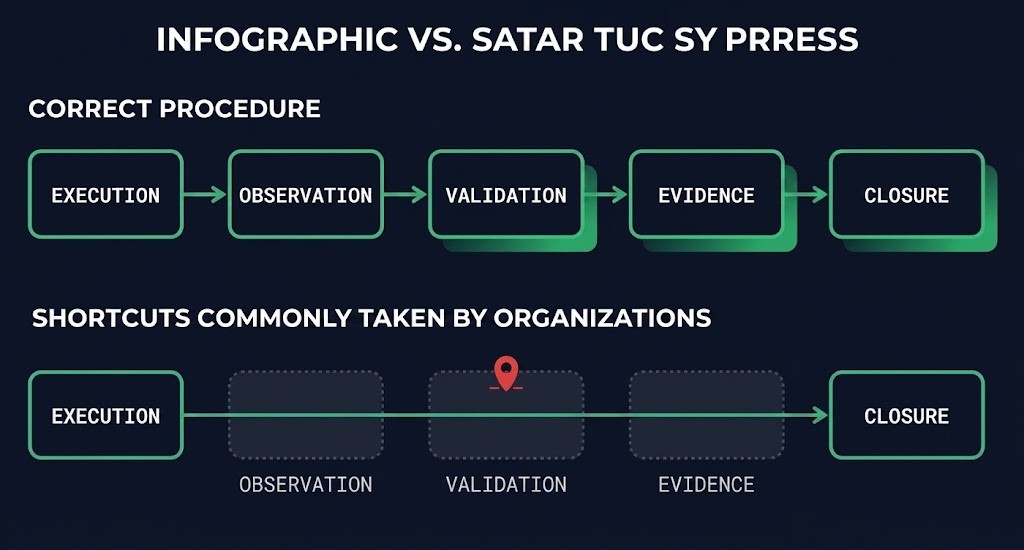
A closure condition that actually closes something needs four things. A design missing any one of them is building premature closure into the architecture on day one.
VERIFICATION DISCIPLINE
- Evidence — an artifact proving the end-state exists, not just that the process ran
- Validation — an independent mechanism checks that artifact against the original claim
- Ownership — someone is explicitly responsible for producing and reviewing the evidence
- Time-bounded verification — a system-enforced deadline, not a documented expectation, forces the check to happen
This is the same four-variable shape Emergency Reconciliation Gap already requires at the exception layer — Bypass Authority, Change Latency Budget, Reconciliation Ownership, and Closure Deadline aren’t decorative, they’re what keeps an authorized exception from becoming a permanent one. The Ransomware Survival Architecture stage walks through what this looks like end to end for a recovery program specifically: a restore that’s provably validated, not just scheduled and reported.
Architect’s Verdict
Premature closure isn’t a monitoring gap or a diligence failure. It’s what happens when a closure condition is designed around what’s cheap to measure instead of what actually needs to be true — and every system in this piece proves the state was never checked, only the process.
The real problem isn’t that these signals are wrong. It’s that they’re not lying about anything — they’re accurately reporting execution, and execution was never the claim that mattered. The gap between “the process ran” and “the state exists” is invisible by design, because closing it costs more than shipping the signal that skips it.
Every architecture eventually becomes a system of closure signals. The quality of those signals determines whether the architecture discovers failure immediately or inherits it for someone else to find later.
Additional Resources
View 10 more resources
Editorial Integrity & Security Protocol
This technical deep-dive adheres to the Rack2Cloud Deterministic Integrity Standard. All benchmarks and security audits are derived from zero-trust validation protocols within our isolated lab environments. No vendor influence.
R.M.
Senior Solutions Architect with 25+ years of experience in HCI, cloud strategy, and data resilience. As the lead behind Rack2Cloud, I focus on lab-verified guidance for complex enterprise transitions. View Credentials →
Get the Playbooks Vendors Won’t Publish
Choose the architecture problems you care about. Get field-tested playbooks and frameworks delivered to your inbox.
- > AI Infrastructure & Inference Economics
- > Cloud Strategy & Hidden Cost Models
- > Virtualization & Deterministic Migration
- > Kubernetes, IaC & Modern Infrastructure
- > Data Protection & Recovery Engineering
Zero spam. Includes The Dispatch weekly drop.
Need Architectural Guidance?
Independent review before major infrastructure decisions.
- > Validate assumptions
- > Identify hidden dependencies
- > Quantify migration risk
- > Challenge vendor narratives
Triage · Advisory · Fractional · Direct Hire